AI Agents & Assistants
01Agents that read your systems, take scoped actions and hand off to a person when confidence drops — with tool permissions and an approval step before anything irreversible.
- Tool Use
- Approvals
- Escalation
Asematic delivers AI business automation services in India for teams losing days to repetitive work. Every automation is scoped against a measurable hours-saved target, grounded in your own data, and kept under human review wherever a wrong answer would cost you.
Automation budget
The thresholds every automation must clear on your own evaluation set before it goes live.
The demo lands, everyone is impressed, and eight months later nothing runs in production. It is almost never the model that failed — it is scope, grounding and the absence of a number anyone agreed to measure. This is where projects leak, and what replaces it.
What it costs you
A pilot that impressed the board and shipped nothing
We pick a single workflow with countable volume and a countable error rate, automate that, and prove the saving before anyone discusses a platform strategy.
What it costs you
A chatbot that confidently invents answers
Answers are drawn from your content with citations attached, and the system is built to say it does not know rather than to fill the silence with something plausible.
What it costs you
Staff retyping the same data across four systems
Triggers, transforms and writes wired between your CRM, accounting, storage and messaging tools, with retries, idempotency and a log of every action taken.
What it costs you
An AI budget nobody can attribute to an outcome
We time the manual process before automating it, then report the same measure afterwards. If the number does not move, that is a finding rather than something to explain away.
What it costs you
Customer data pasted into a public chatbot
Personal data redacted before any model call, processing on infrastructure and accounts you own, retention configured deliberately, and every request logged for audit.
What it costs you
Output that quietly degrades after a model update
Prompts live in source control and every change runs against a held-out evaluation set, so a regression is caught in the pipeline rather than by a customer complaint.
A document pipeline and a customer-facing agent are different problems. They get the same evaluation discipline, the same escalation path and the same cost metering.
Agents that read your systems, take scoped actions and hand off to a person when confidence drops — with tool permissions and an approval step before anything irreversible.
Invoices, purchase orders, contracts and forms read, extracted and validated into structured records, with confidence scores that route edge cases to a human queue.
Cross-system processes wired end to end — trigger, transform, write, notify — with retries, idempotency and a complete log of every step the automation took.
WhatsApp, web and in-app assistants grounded in your knowledge base, with handover to your team carrying the full conversation context rather than restarting it.
Lead scoring, demand forecasting, churn signals and routing models trained on your history, delivered as an API your existing systems can call.
Adding retrieval, drafting and summarisation to the CRM, ERP or portal you already run, so people gain the capability without learning another tool.
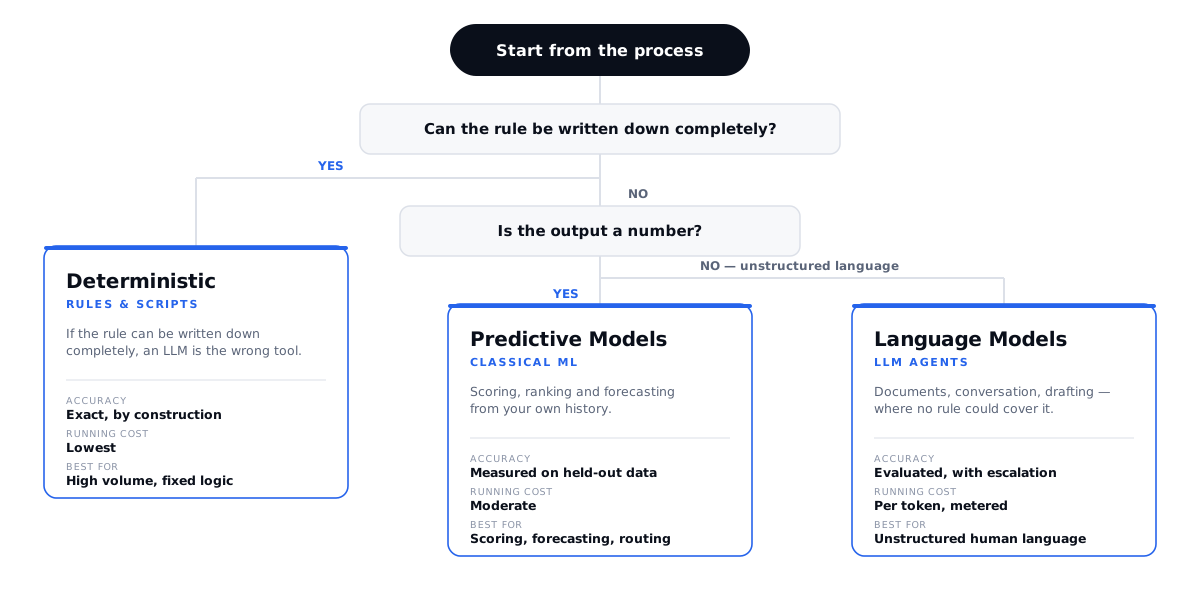
A lot of what gets sold as AI is a rule that could have been written down. We choose the cheapest technique that clears the accuracy bar, and we will tell you when that means no model at all.
Choose when the process never varies
If the rule can be written down completely, a language model is the wrong tool. Scripts and workflow engines are cheaper, faster and exactly correct every time.
Choose when you need a number
Scoring, ranking and forecasting from your own history. Cheaper and far more explainable than a language model when the output is a probability rather than prose.
Choose when the input is unstructured
Documents, conversation, drafting and summarisation — where the input is messy human language and no rule could cover it. Grounded, evaluated and escalated by design.
These fifteen items are not line-items on a quote. They ship with every automation we build, on every engagement model, because AI without evaluation, oversight and cost control is a liability rather than a capability.
We pick per task, from a short list we know deeply, and we are not loyal to a provider. Model choice is a cost and accuracy decision that gets revisited as the field moves.
The baseline is timed before anything is built, and feasibility is proved on your real cases in week three. Each stage closes with a named deliverable you review.
We sit with the team, time the tasks that eat the day, and score each one on volume, minutes consumed and error rate. The output ranks what is worth automating and what is not.
Deliverables
Before committing to a build, we assemble an evaluation set from your real historical cases and prove the approach clears the accuracy threshold on it. If it does not, you find out in week three.
Deliverables
The automation is built against your systems, grounded in your data, and wrapped in the permissions, logging and escalation paths it needs before anyone trusts it with live work.
Deliverables
It runs alongside your team first, producing output nobody acts on, so accuracy can be compared against real decisions. Only then does it move to supervised, and then to autonomous.
Deliverables
We re-measure the baseline from week one and report the difference in hours. Where the saving is real, we take the next item off the scored list; where it is not, we say so.
Deliverables
Scope determines the model, not the other way round. Most clients start with a single fixed-scope automation, because it proves the economics before anything larger is committed.
One process, one measurable outcome
A single workflow scoped, built and measured against its baseline for a fixed price. The usual starting point, because it proves the economics before you commit further.
A backlog of processes worth automating
A monthly block of engineering working down the scored opportunity list, plus monitoring, evaluation upkeep and tuning of what is already running.
AI capability built into the product itself
Engineers assigned full time to build AI features inside your product, working in your repository, stand-ups and release process rather than alongside them.
Every quote is fixed against a written specification, so the number you approve is the number you pay.
The questions operators actually ask before commissioning AI automation work, including whether the process is worth automating at all.
Cost tracks the number of processes and the depth of system integration rather than any per-user fee. A single scoped workflow — document extraction, or a grounded support assistant — sits in a very different bracket to agents acting across your CRM, accounting and messaging stack. We scope during the process audit and quote a fixed figure against a written specification, with running model costs metered separately and visible to you.
The ones with high volume, meaningful minutes per task, and a measurable error rate. We time the work during the audit and score every candidate on those three dimensions. The result usually surprises people: the process everyone complains about is often not the one costing the most hours. You get the ranked list whether or not you proceed with the build.
That is not what we build or what we recommend. The automations that pay back reliably remove repetitive work: data entry, extraction, first-line triage, routine drafting. The same team then handles more volume and spends its time on judgement. We measure success in hours returned, not roles removed, and every consequential action keeps a human approval step.
Three ways. Answers are grounded in retrieval over your own documents with citations, so output is traceable to a source. The system is built with an explicit refusal path, so it declines rather than invents. And every change runs against an evaluation set drawn from your real cases, so accuracy is a number we monitor rather than an impression. Anything below the confidence threshold escalates to a person.
Your data is not used to train anybody's model. Personal data is redacted before any model call, processing runs on infrastructure and provider accounts you own, and retention is configured deliberately rather than left at a default. Every request is logged for audit, and where a workload is sensitive enough we run open-weight models inside your own boundary so nothing leaves it.
Yes, and that is usually the point. We integrate with your CRM, ERP, accounting, storage and messaging tools over their APIs rather than asking your team to adopt another interface. Where a system has no API, we work through database access or scheduled file exchange. Adding retrieval and drafting inside a tool people already open every day is far more likely to be used than a new tool beside it.
We time the manual process before automating it, and that baseline becomes the measure. After rollout we report the same measure — hours consumed, tasks handled, error and escalation rate — against it. If the number has not moved, that is reported as a finding rather than explained away. We then look at whether the process was the wrong candidate or the approach was.
The feasibility result lands in week three, before the main build is committed. A first automation is typically live in shadow mode by week eight and running supervised by week nine, with the hours-saved comparison in week ten. Starting with one scoped process rather than a platform programme is what makes that timeline realistic.
An automation is only as useful as the systems it can reach and the data it can trust. These are the pieces that usually sit either side of it.
Describe the process your team repeats most, or the AI pilot that stalled. You will get an honest read on whether it is worth automating, which technique fits, and what the saving would realistically be — before any commitment.